A little context on how I got here.
I have a degree in Anthropology, spent years in retail leadership, kitchen operations, and somehow ended up in quality systems for a large manufacturing company. On paper, those things don't seem particularly related. In practice, they all involved the same thing: people, systems, and trying to understand why things happen the way they do and then to improve them.
I've never been particularly attached to a specific discipline or job title. If anything, I've spent most of my career accidentally wandering into boxes other people created for me. Quality was one of those boxes. Retail was another. They were jobs I held, but they were never “me”. What was always “me” was the need to understand why.
Why does this process exist?
Why do we do it this way?
Why did that decision make sense at the time?
Why does the explanation not match the outcome?
Curiosity has been the only constant. The job titles were just the scenery.
I've always been drawn to friction. Not in a "Traci loves chaos" sort of way, but in a "I can feel in my bones that something isn't adding up, the math isn't mathing" sort of way. I need to understand how systems work, how people interact with them, and what happens when reality doesn't match the story being told. If a process produces an outcome that nobody likes, my first instinct is usually not to accept it but to start asking questions.
What assumptions are we making?
What are we actually trying to accomplish?
What are we measuring?
How do we know those measurements mean what we think they mean?
Who decided those measurements were the correct ones?
I don't know whether I think differently than most people. I've never had access to anyone else's brain. What I do know is that when I encounter contradictions, my attention tends to get stuck there until I understand them.
Over the last several months, while navigating the job market and talking to people on both sides of the hiring process, I found myself running into the same kinds of questions I had encountered in other systems throughout my career. The more conversations I had, the more I noticed a pattern. Different industries, different goals, different stakeholders, but usually the same underlying assumptions. That's what led me here. I didn’t set out to study hiring and I don’t have some grand theory. But I started feeling friction and did what I always do when something doesn't quite make sense: I started pulling on the thread.
What started all of this was an observation I made while trying to navigate the job market as a somewhat more senior, hard-to-classify, but highly adaptable and capable worker. Thousands of roles, hundreds of applications have yielded two interviews, countless rejections and a part-time job to keep the fires burning. On the flip side, I’ve gotten hundreds of recruiter emails and calls, none convert. I see tons of articles about companies struggling to find good candidates, and exponentially more candidates discussing jumping through multiple sized hoops, only to be rejected or ghosted. Those two complaints seem to be mutually exclusive, unless there is an underlying cause to the friction. Just in the last 24 hours, I had a hilariously tragic contact from a recruiter.
I got an email with a very detailed job posting. They explained they had reviewed my resume and believed I was a good fit and asked if I’d be interested. I reviewed the information and believed I could have brought a lot of value to the role but I did have some yellow flags I wanted addressed before wasting anyone’s time. So I replied with my current resume (which was exactly the same one they had reported to have reviewed, it hasn’t changed) and a short list of questions I wanted clarified. The response I got back within five minutes - “Thank you for the response. Let me check once with manager about your profile And will get back to you if they are interested.” No response to my questions, no feedback; the recruiting equivalent of Homer Simpson backing into the hedge. What struck me wasn't the rejection. It was the sudden shift in certainty. A few minutes earlier, I had been contacted because they had reviewed my resume and believed I was a good fit. After receiving the same resume and a handful of questions, the conversation changed to whether the manager would be interested in my profile at all. What had changed?
Did they not actually review my resume before reaching out?
Did an automated system identify enough matching criteria to flag me as a potential candidate?
Did my questions reveal something that wasn't obvious from the resume alone?
Was I suddenly viewed as too senior, too broad, or too difficult to classify for the role?
I don't know. I don’t like not knowing.
I can't tell which part of the process produced the original conclusion and which part produced the second one. That missing rationale is wholly unacceptable to my brain.
I have been all in on the job search for roughly five months at this point. You could say pattern recognition is my super power. So when I see not just the same roles being posted over and over, but being sent TO ME as a possible fit after they have already turned me down, I’m sorry, but the cynic in me calls BS.
Not because I think every rejection is wrong or that every role is secretly perfect for me, but because repeated observations eventually force a question.
What information did my questions reveal that my resume did not?
If my profile was compelling enough to justify outreach, what caused it to become uncertain the moment I engaged?
Was the original conclusion reached by a person, a process, or an algorithm?
If a role wasn't a fit yesterday, why is it a fit today?
If a company has already evaluated my background and decided not to move forward, why am I receiving automated recommendations for similar (or identical) positions?
If the system is learning, what is it learning?
And if it isn't learning, what exactly is all of this data being collected for?
When I was a hiring manager and I reviewed a candidate that wasn’t right for a role but that I really saw potential with, I found a place to put them. Why are companies “keeping me on fill for future opportunities” that never arrive? We have more data than ever, more technology than ever, more tracking than ever, and yet the practical outcome often feels less personalized than it did when a manager was simply keeping a mental note about a promising candidate. Has anyone validated that this newer approach produces better outcomes than the older one?
In every system I have worked in, trust increases as evidence accumulates. In materials and chem; as quality evidence accumulates, trust increases and quality gates relax. In release; as process reliability increases, we move from controlled to positive to continuous release. The system learns and then adapts. Hiring appears to not follow this pattern and creates a question I can't stop coming back to:
Why does demonstrated reliability reduce scrutiny in some systems but increase it in others?
The answer I keep circling is that the system may be designed against the wrong definition of success. Logically, I’d assume that a hiring system is optimized to put the candidate most able to do the job and do it well in the role. But is it? Before a system can be successful we need to understand what success is, whose definition of success we're using, and what underlying assumptions we're making.
"Success" isn't a universal concept inside an organization. A hiring manager struggling to cover a critical workload may define success as finding someone who can contribute as quickly as possible. Operations may define success as keeping projects moving and deadlines from slipping. Finance may be more concerned with controlling costs, minimizing turnover, and avoiding expensive hiring mistakes. HR may be focused on creating a process that is consistent, compliant, and defensible. Recruiters may be measured on how quickly they can fill a requisition or maintain a healthy candidate pipeline. None of those goals are inherently wrong. In fact, most of them are perfectly reasonable. The problem is that they are not necessarily the same goal and would value wildly different candidates.
A process that is highly successful at reducing risk may not be highly successful at identifying exceptional talent. A process that is highly successful at maintaining consistency may struggle with people who don't fit neatly into predefined categories. A process optimized for speed may sacrifice depth, while a process optimized for depth may become too slow to meet business needs.
What struck me is that everyone involved may be acting rationally according to their own definition of success, while still contributing to outcomes that leave everyone frustrated. Employers report difficulty finding talent. Candidates report difficulty finding opportunities. Recruiters are overwhelmed. Hiring managers remain understaffed. Yet each individual part of the system may be achieving exactly what it was designed to achieve.
That possibility led me to a question I couldn't shake:
What if the problem isn't that the system is failing but instead is succeeding according to the wrong definition of success?
It had never occurred to me to ask what the system was actually optimizing for. Once I did, the next question followed naturally: how do those objectives get translated into measurable criteria, and how do we know those criteria remain predictive of the outcome they're intended to represent? In today's hiring environment, expecting organizations to fully evaluate every candidate in depth simply isn't realistic. The volume of applicants, the pace of business, and the limits of human attention make some form of simplification inevitable. Faced with more information than they can reasonably process, organizations do what humans have always done: they simplify. Humans are remarkably good at classifying things, (we classify everything) not because we're lazy but because the world is too complex not to. Just stop and hink about how many boxes we create every day:
Introvert / Extrovert
Liberal / Conservative
Smart / Dumb
Friend / Stranger
Safe / Dangerous
Success / Failure
Employee / Management
Beginner / Expert
Urban / Rural
High Performer / Low Performer
Red State / Blue State
Cat Person / Dog Person
Millennial / Boomer
ADHD / Neurotypical
Married / Single
Citizen / Foreigner
Good Neighborhood / Bad Neighborhood
And then the really powerful ones:
Credit Score
GPA
Net Worth
Performance Ratings
Polling Numbers
Economic Indicators
None of these things are the thing.
They're proxies.
A credit score doesn’t prove trustworthiness any more than a GPA proves intelligence or a resume proves capability. They're all attempts to compress something enormously complicated into something manageable. The boxes aren't inherently bad, in fact, they're necessary. No one can evaluate every person, supplier, process, or decision from first principles every single time. The boxes are important tools but they are proxies and the problem begins when we forget that they are. Once we start mistaking the proxy for the reality, we begin measuring success by the proxy rather than the outcome it was intended to represent.
If we have hiring systems that are processing massive amounts of candidates in record time, but still have empty seats and unemployed candidates, is it really working or is it just being measured against the wrong proxy? Candidate throughput is easy to measure. Successful matching is much harder. How do we even define it? Is it offers accepted? Employee retention? Performance ratings? Time with the company? Promotion rates? Business impact? Some combination of all of the above?
Some metrics measure how efficiently applications move through a system while some my measure the durability of the outcome it. That distinction matters. A process can be highly efficient at producing activity without being particularly effective at producing results. The more we optimize around the measurement itself, the greater the risk that we drift away from the reality we were originally trying to improve. One signal that this may be happening is the behavior of the people interacting with the system. When people trust a process to produce the outcome they want, they tend to use it. When they don't, they start looking for alternatives.
I believe this is why a separate phenomenon has emerged.
Automation was introduced to improve efficiency, reduce bias, standardize evaluation, and create more objective hiring processes. Yet much of the advice given to job seekers today centers on bypassing the formal process altogether:
Network aggressively
Obtain referrals
Contact hiring managers directly
Leverage personal connections
Build visibility outside the application system
These approaches may be effective, but their growing importance raises some valid questions.
If the formal process is the preferred path, why are so many successful outcomes occurring outside of it?
If the hiring system is functioning as intended, why are so many candidates and employers actively seeking ways around it?
Those questions led me to a broader thought.
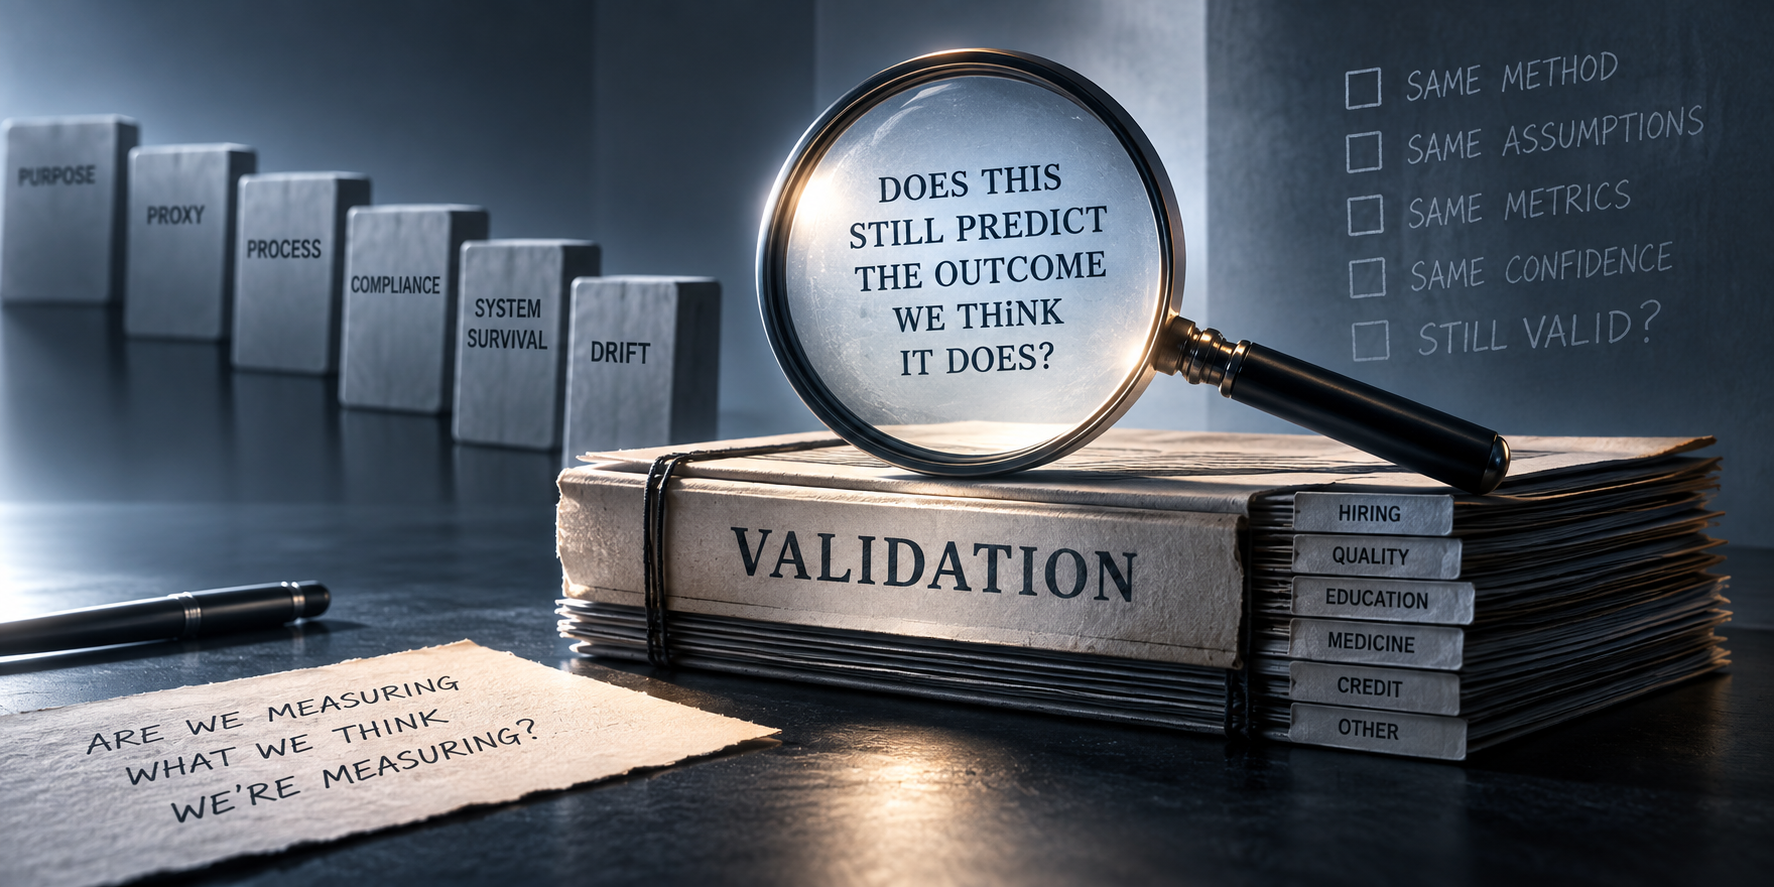
Are we measuring drift? How often do we validate the validation itself?
Across industries, we spend considerable effort validating processes, controls, documentation, workflows, and decision criteria. We verify that systems operate according to specification. What we examine less frequently is whether those validation methods remain predictive of the outcomes they were designed to achieve.
One quality example illustrates the concern:
Imagine an organization experiences 400 similar failures.
In the first scenario, all 400 failures are classified as the same issue.
The result is straightforward:
1 failure repeated 400 times = 400 repeat failures
The metric indicates a significant recurring problem.
Now imagine the same 400 failures are reviewed through a more granular classification system: additional categories, subcategories, and failure codes are introduced. Each event is now assigned to its own narrowly defined bucket.
The result now appears very different:
400 failures classified as 400 unique events = 0 repeat failures
The organization still experienced 400 failures, the operational burden hasn’t changed, the customer impact hasn’t changed. The resources required to investigate and address those failures haven’t changed. What changed was the classification system. New boxes were introduced, and the same underlying reality was redistributed among them. From a reporting perspective, the metric appears dramatically improved. Repeat failures have seemingly disappeared. Yet nothing about the actual performance of the system necessarily improved. The outcome changed because the measurement framework changed.
That distinction is important. Organizations often spend considerable effort validating the accuracy and consistency of classifications while spending far less time asking whether the classification system itself remains predictive of the outcome being measured.
Most systems are validated at the moment they are created. Far fewer are re-validated once they become entrenched. Over time, processes accumulate assumptions, metrics become targets, categories become more granular, new controls are added and new screening criteria are introduced. Individually, each change may appear reasonable. Each may even solve a legitimate problem. But these changes don’t operate in isolation, they are incorporated into an existing system where they interact with every control, metric, requirement, and decision point already in place. The cumulative effect of these changes can move a system further and further away from the outcome it was originally designed to achieve, even while every individual modification appears justified.
The question is not whether the process is functioning as designed.
The question is whether the design itself remains predictive.
Systems don't usually fail because of one bad decision. They fail because of hundreds of individually reasonable decisions that were never evaluated together. Death by a thousand papercuts.
Case Study: Grades and GPA
The original problem was simple: How do we evaluate whether students are learning?
To solve that problem, schools created a grading system where students were assessed, assigned scores, and grouped into categories.
For many years, the system was straightforward:
90-100 = A
80-89 = B
70-79 = C
60-69 = D
Below 60 = F
The boxes were easy to understand. They represented a proxy for learning.
Over time, many schools modified those boxes. Some adopted weighted grading scales. Some changed how scores were calculated. Some implemented minimum grades for completed work. Others adjusted scoring systems to reduce the impact of missed assignments or to address concerns about student outcomes.
Each change had a rationale (a documented one? Who knows.)
Each change attempted to solve a problem.
But they didn’t ask the most fundamental of questions:
If the boxes change, what happens to the meaning of the outcome?
If a student receives a "B" today, does it represent the same level of mastery it represented twenty years ago?
If graduation rates increase, does that necessarily mean learning increased?
If average grades rise, are students learning more, or have the measurements changed?
The purpose of the example isn’t to argue that any particular grading system is right or wrong but to ask how often do we revisit the relationship between the measurement and the outcome it was designed to represent? At what point do we stop validating student learning and start validating the grading system itself?
Case Study: Medical Diagnosis
The original problem was simple: How do we understand, communicate, and treat illness across millions of patients?
To solve that problem, medicine developed diagnostic categories. Patients with similar symptoms, test results, and clinical presentations were grouped into defined conditions and assigned a diagnosis.
The boxes served an important purpose. Without them, research would be difficult, treatment protocols would be inconsistent, and communication between providers would be nearly impossible.
The diagnosis became a proxy for a much more complex reality. Each patient is unique but the diagnosis is the box we put them in. Over time, diagnostic criteria evolve: new conditions are recognized, existing conditions are subdivided, categories are merged, expanded, or redefined as new information becomes available. Again, each change has a rationale and attempts to improve understanding and patient care. But the question remains the same: How often do we revisit whether the category remains predictive of the outcome it was created to support? Two patients may share the same diagnosis and respond very differently to the same treatment. One may improve rapidly while the other may not improve at all. The diagnosis is still useful, but it’s not the patient. The purpose of the category is to improve outcomes, not to replace observation, judgment, or individual context.
The question is not whether diagnostic categories are valuable.
The question is whether we remember that the category is a proxy for reality rather than reality itself.
Case Study: Credit Scores
The original problem was simple: How do lenders evaluate risk across millions of borrowers?
Reviewing every individual's full financial history would be slow, expensive, and inconsistent. To solve that problem, financial institutions developed credit scoring systems. The score provided a proxy: a single number that could represent a complex history of borrowing, repayment, utilization, and financial behavior. The box served an important purpose: It allowed decisions to be made quickly and consistently. Over time, scoring models evolved. Variables were added, removed, weighted differently, and refined as lenders sought to improve predictive power. And once again, I have to ask about intent.
What outcome is the score intended to predict?
The ability to repay a loan?
Financial stability?
Responsibility?
Trustworthiness?
These concepts overlap, but they are not identical. A credit score is not a person. It doesn’t show work ethic or financial literacy. It is a proxy designed to estimate risk under a specific set of assumptions.
The question is not whether credit scores are useful.
The question is whether we remember that the score represents a model of reality rather than reality itself.
Just like with grades and diagnoses, the box exists to help us understand something complex. Problems emerge when the box becomes more important than the thing it was created to represent.
I don’t believe this phenomenon is accidental. Systems, like organisms, adapt. Over time they respond to incentives, constraints, risks, and pressures in their environment. Changes that improve survival tend to persist. Changes that do not tend to disappear. Viewed through that lens, the drift described throughout these examples becomes easier to understand.
A hiring system may begin with the goal of finding the best talent. Over time, however, it may increasingly optimize for legal defensibility, consistency, cost reduction, recruiter workload, time-to-fill metrics, or compliance reporting.
A school system may begin with the goal of measuring learning. Over time, it may increasingly optimize for graduation rates, standardized testing outcomes, funding requirements, or administrative performance metrics.
A healthcare system may begin with the goal of improving patient outcomes. Over time, it may increasingly optimize for documentation requirements, reimbursement structures, risk reduction, or regulatory compliance.
None of these changes are inherently irrational. In fact, many are entirely reasonable. The challenge is that what helps a system survive is not always identical to what helps it achieve its original purpose. I believe that is why validating the validation matters so much. The question is not simply whether a system is functioning as designed. The question is whether the system remains aligned with the outcome it was originally created to achieve. If it doesn’t, we may find ourselves optimizing increasingly sophisticated proxies while drifting further away from the reality they were intended to represent. With that in mind, validating the validation becomes less about hiring, grading, healthcare, or credit scores specifically. It becomes a broader question about how systems evolve. If systems naturally adapt toward whatever helps them survive, then periodic re-examination of our proxies, metrics, and validation methods may be necessary to ensure survival and purpose remain aligned. Otherwise, a system can become extraordinarily good at preserving itself while gradually losing sight of the outcome it was originally created to achieve.
FIELD NOTE · FN-06 · VALIDATE THE VALIDATION